
This is the internal architecture of Amazon S3.
Amazon S3 is an object store that manages exabytes of data across millions of hard disk drives. At this scale, reliability is achieved by assuming failure is constant, isolated, and invisible to customers.
This explains how S3 works internally, with all relevant references mentioned at the end.
1. Upload path
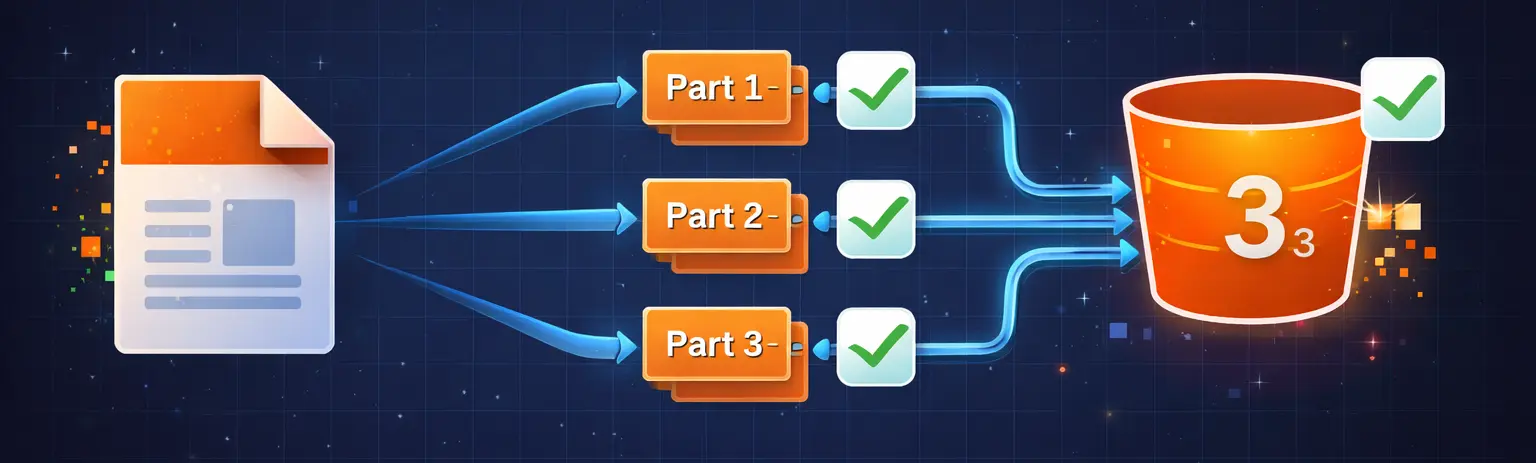
When a user uploads a file to S3, the system:
breaks the object into** **multiple parts
uploads each part** **in parallel
checks every part with its checksum
This design ensures performance and fault tolerance.
2. Continuous monitoring
Data is never assumed to be safe. S3 runs continuous background monitoring across its entire disk fleet:
Hard drives are constantly scanned
If a hard drive fails, it is removed from service
Data is reconstructed from surviving fragments
Replacement happens in parallel across replicas, or other chunks with error-correcting codes.
Because object data is stored redundantly, read requests do not stall during repairs.
3. Shuffle sharding
Instead of binding data or traffic to fixed resources, Amazon S3 uses shuffle sharding:
every object is assigned a random subset of servers
results in roughly even distribution
avoids a single point of failure
retries almost always land on healthy servers
If a request is slow, the client runtime can cancel it preemptively and retry elsewhere, maintaining low tail latency.
4. Auto-scaling
Keys are partitioned by prefix. When a prefix becomes hot:
S3 splits the shard
More servers are added behind that prefix
Load is redistributed automatically
This allows S3 to scale metadata and request handling without customer intervention.
5. Avoiding Read Hot Spots
Most S3 reads target recently written data. If a new shard received only new objects, it would become a read hotspot.
Instead, S3 first populates new shards with older data to manage its peak request rate.
This distributes load evenly, avoiding a read hot spot.
6. Fault Tolerance (99.999999999% Durability)
S3 uses error-correcting codes:
A file is split into data fragments (D1, D2, D3, D4, D5).
Additional parity fragments are computed (P1, P2, P3, P4).
The loss of any three fragments is now tolerable. (Any six of the total nine fragments are sufficient to reconstruct original data)
This allows S3 to tolerate multiple simultaneous failures while using only ~1.8x storage overhead, instead of 3x or more with simple replication.
Amazon S3 also has regional fault tolerance, with object fragments spread across multiple availability zones.If an entire AZ fails, requests are transparently routed to healthy zones.
Conclusion
Amazon S3 is designed for scale and reliability. The AWS engineers are obsessed with highly predictable performance (even more than optimising systems!).
If you want to know more about distributed systems and system design, try the detailed course at InterviewReady.
https://interviewready.io/course-page/system-design-course
Cheers!
References:
Amazon S3 Internal Architecture: https://aws.amazon.com/awstv/watch/d33eda30e60/AWS S3 Architecture: https://www.youtube.com/watch?v=NXehLy7IiPMAWS S3 Internal Archicture (Recent Video): https://www.youtube.com/watch?v=JNN5Aw5kVFIShort Video: https://www.youtube.com/shorts/M2jYafYJovo


