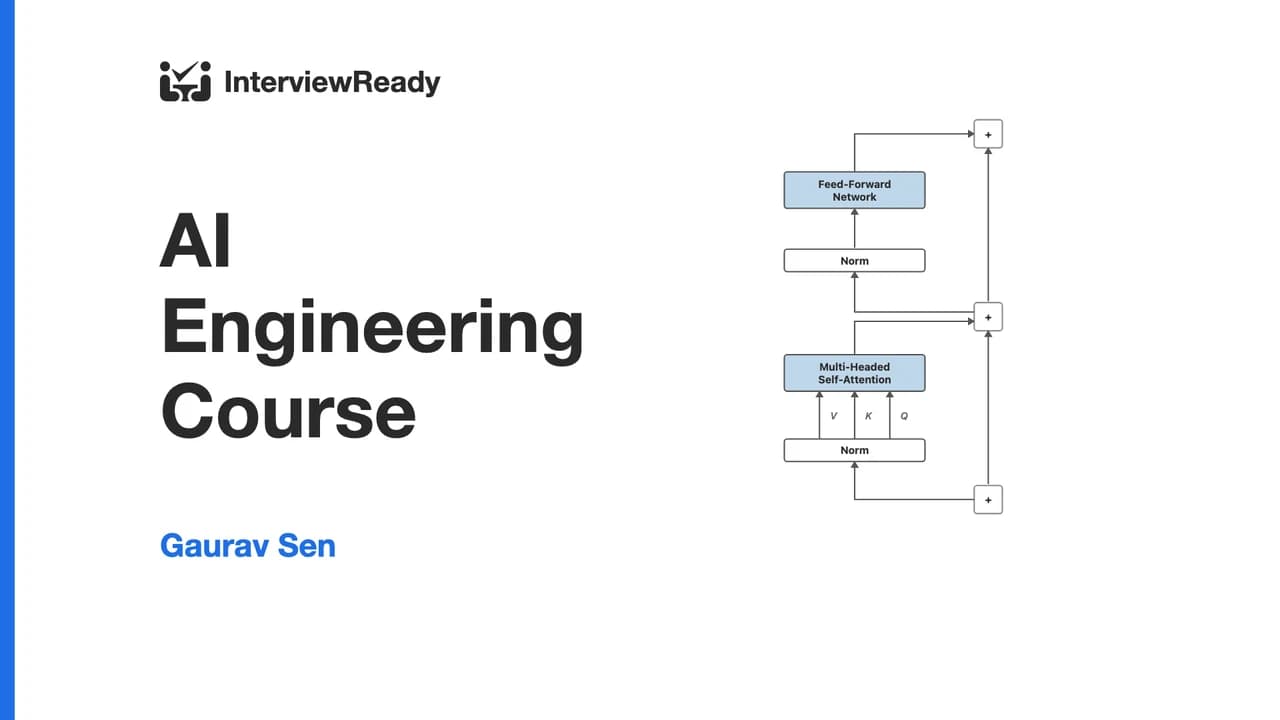
This chapter explains how Flash Attention improves the performance of LLMs by optimizing how they use GPU memory.
Previous chapters covered techniques like KV caching and Mixture of Experts to improve efficiency.
Flash Attention specifically targets how memory is handled during attention computation.
Transformers run on GPUs, which execute many instructions in parallel and use specialized fast memory.
The bottleneck is the slow transfer from main memory (DRAM) to the GPU’s SRAM.
Flash Attention reduces the number of memory reads and writes by fusing operations.
This makes attention layers faster and more memory-efficient, which helps scale large models.
The key insight is that Flash Attention is about better hardware-level utilization, not changing the model architecture.