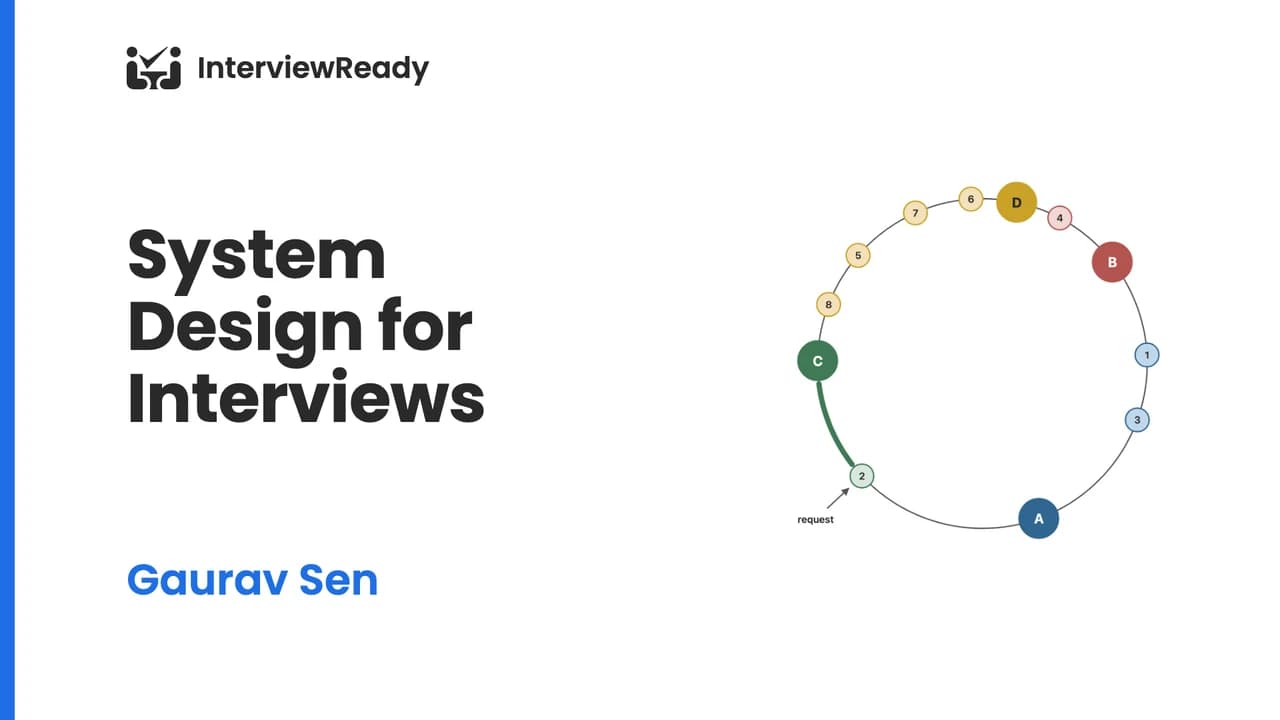
Gaurav discusses using consistent hashing in sharding and how requests are mapped to specific buckets in some distributed systems like Redis. There is a potential for one bucket to become overloaded due to a lack of uniform distribution.
What is the potential latency when consumers pull during a load rebalancing event?
Graph API vs. Open API.
There are various ways to overcome the problem of an increase in logs, including compressing and archiving logs, scaling the storage for logs, and identifying which service is causing the increase in logs. It is impossible to stop an increase in logs as user activity increases, but steps can be taken to manage them more efficiently. Additionally, discussing with teams why they are logging so much is a practical consideration.
The use of APIs and understanding how they work are essential. GraphQL may not be as helpful as REST in certain situations and clients must understand the objects beforehand.
When there is a large request load on the API gateway, it can be scaled horizontally to handle the load, but that code can also be made more efficient. YouTube handles a similar scenario, but when there is too much load, the cached content can be used. There is a need to change and degrade the service in the API gateway when there is too much load.
Gaurav shares his experience preparing for technical interviews, specifically for DSA. It's difficult to find an equilibrium between system design and DSA prep. It's essential to speak with the interviewer about their thought process and approach to a problem. For DSA, execution is very important, and being able to understand and catch hints is also essential. In an interview, it's best to be prepared and not overlook the importance of paying attention to the current needs.
One complex DB query as an API versus using three different simple queries as three APIs: depends on the requirement, but usually, three simple queries are better, but sometimes it may be necessary to use one complex query for an atomic operation.
We found a solution for handling large requests and responses for an API. The idea of breaking down a large request into smaller fragments and returning responses is applicable here. The input and decision on how to break down the request can depend on the business use case and that there is a separation of ingestion rate and persistence rate. We may also use an asynchronous approach, where data is uploaded and inserted into a database after all files have been processed and cross-checks can be made on the records.