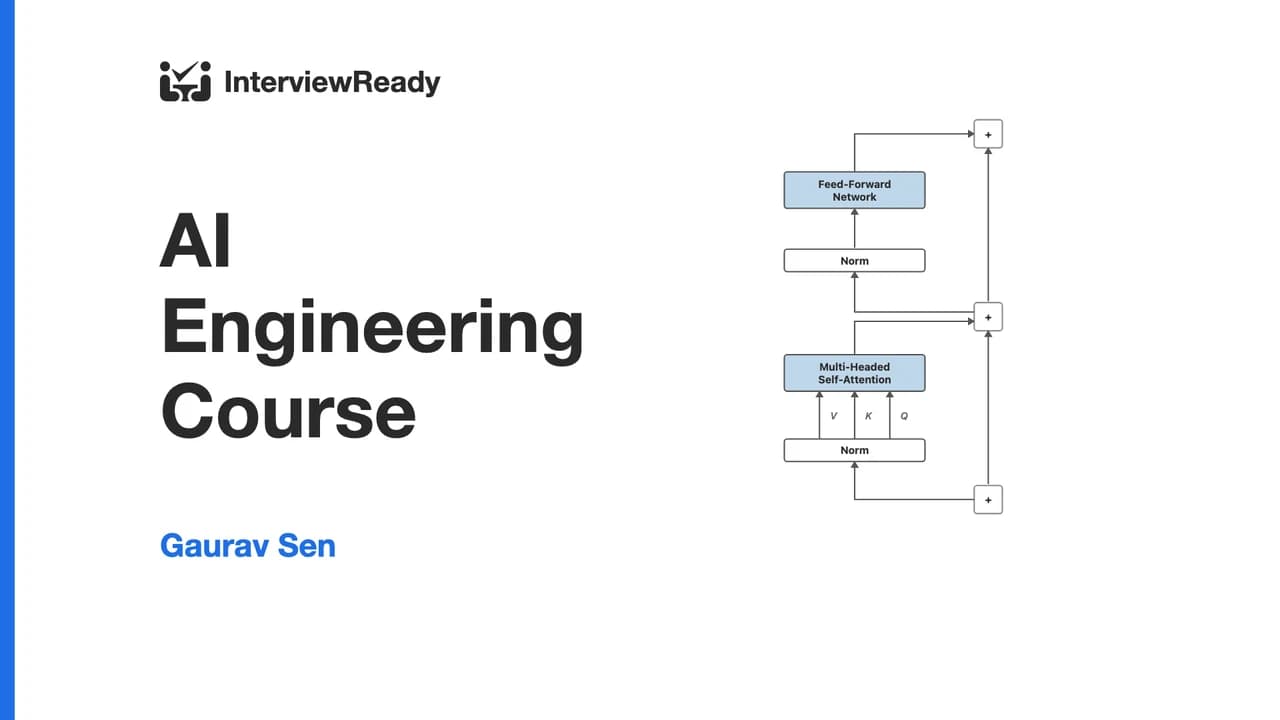
This chapter explains how key-value caching helps optimize the performance of large language models.
Transformers have hundreds of billions of parameters, including query, key, and value matrices.
During generation, each new token usually requires reprocessing all previous tokens, which is inefficient.
Key-value (KV) caching solves this by storing the keys and values computed during previous steps.
When generating the next token, the model only processes the new input and reuses the cached data.
This significantly reduces compute time and memory usage, especially during long sequences.
The core idea is that KV caching improves inference efficiency without changing the model’s accuracy.