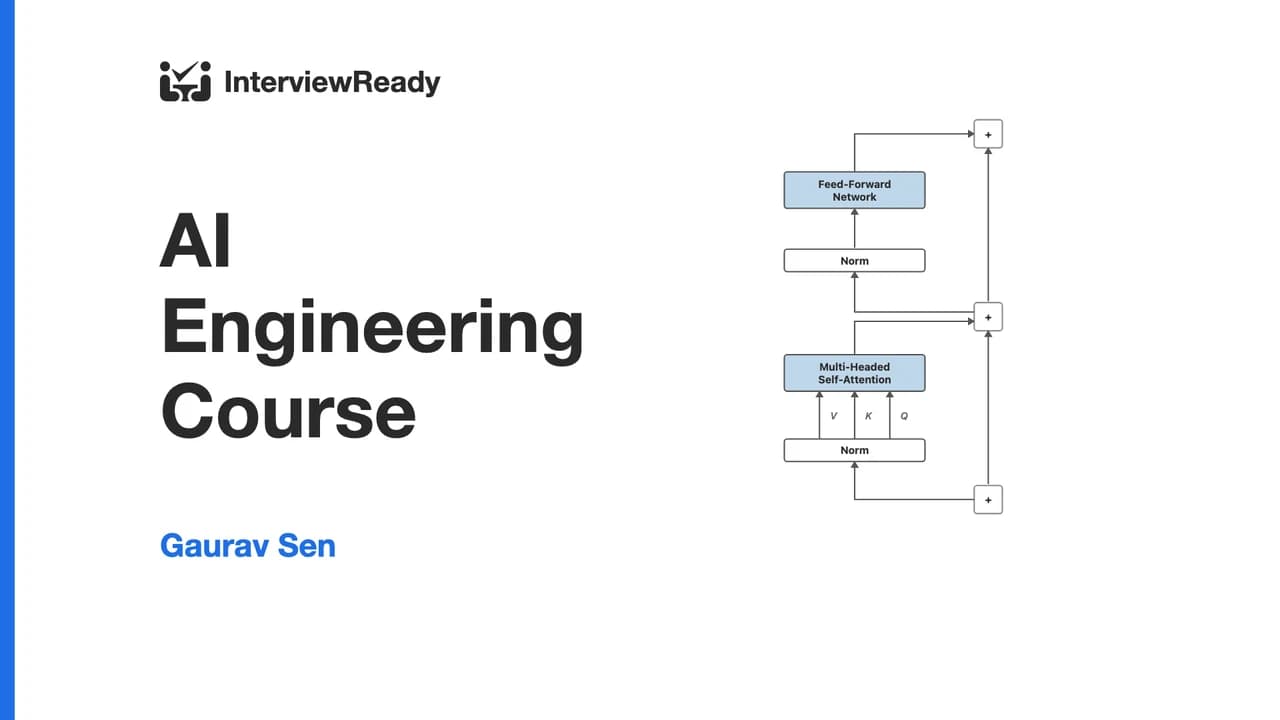
We’re kicking off our deep dive into the internals of Large Language Models by breaking down the Transformer architecture into three core parts. This video focuses on the first part: Positional Embeddings.
You’ll learn:
Why do transformers need positional context
How vectors are combined with position to form inputs
What changes when the same word appears in different positions
This is the first step in the transformer architecture.
Next up: Attention.